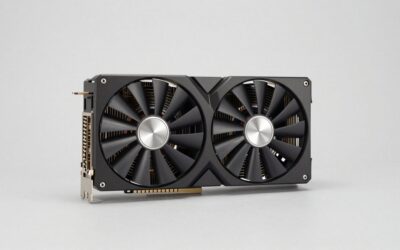
Quick answer: For most people in 2026, the best graphics cards (gpus) for machine learning is the ASRock Radeon RX 7600 Challenger Pro 8GB OC — our #1 rated choice. See the full ranked comparison, alternatives and buying advice below.
- The Short Answer
- Top 3 Picks
- Quick Comparison
- How We Chose
- 1. ASRock Radeon RX 7600 Challenger Pro 8GB OC – Best for Budget Entry into ML
- 2. NVIDIA Tesla K40 – Best for Legacy Kepler Compute on a Tight Budget
- 3. NVIDIA Tesla V100 Volta 32GB – Best for Affordable Tensor-Core Training Power
- 4. Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo – Best for Maximum VRAM Capacity
- 5. GIGABYTE Radeon AI PRO R9700 AI TOP 32G – Best Overall for Modern ML Workstations
- 6. PNY NVIDIA A2 16GB Ampere AI Graphics Card – Best for Low-Power Inference
- How to Choose
- Frequently Asked Questions
- Final Recommendation by Situation
- Related Guides
The Short Answer
The best graphics card for machine learning in 2026 is the GIGABYTE Radeon AI PRO R9700 AI TOP 32G for most people who need a serious workstation-class accelerator with a single purchase, because its 32GB of GDDR6 and modern ROCm support cover the widest range of real training and inference workloads without forcing you into a multi-card setup. If your budget is tight and you are running small vision models, fine-tuning adapters, or learning the tooling, the ASRock Radeon RX 7600 Challenger Pro 8GB OC gets you a working, driver-supported GPU for entry-level work. If raw memory capacity per dollar is the priority and you are comfortable with community-maintained drivers, the Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo offers the largest VRAM pool here. This guide compares VRAM capacity, CUDA vs ROCm support, memory bandwidth, power draw, multi-GPU scaling, and value across model workloads so you can match a card to what you actually run.
Top 3 Picks
Best overall: GIGABYTE Radeon AI PRO R9700 AI TOP 32G. A modern, vendor-positioned AI accelerator with 32GB of GDDR6 and a turbo-fan cooling system, it handles mid-size transformer fine-tuning, diffusion training, and large-model inference without the age penalty of older datacenter cards. It is the safest single-card bet for a 2026 ML workstation.
Best budget: ASRock Radeon RX 7600 Challenger Pro 8GB OC. An RDNA 3 card with 8GB GDDR6 and PCIe 4.0, it is the cheapest legitimate entry into GPU-accelerated ML. You learn the stack, run small models, and infer on quantized networks, accepting that 8GB is a hard ceiling.
Best premium / best for maximum VRAM capacity: Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo. A dual-GPU-style card presenting a 48GB memory pool, it is the pick when your model simply will not fit on 24 or 32GB and you want one physical slot to hold the weights.
Quick Comparison
| Product | Best for | Key specs | Price tier |
|---|---|---|---|
| ASRock Radeon RX 7600 Challenger Pro 8GB OC | Entry-level learning and small-model inference | RDNA 3, 8GB GDDR6, PCIe 4.0, triple-fan, 0dB silent mode, 2695MHz boost | Budget |
| NVIDIA Tesla K40 (900-22081-2250-000) | Legacy Kepler compute, single-precision FP32 tinkering | Kepler-class datacenter GPU, ~12GB GDDR5 class, passive server cooling | Budget |
| NVIDIA Tesla V100 Volta 32GB | FP16 tensor training from the Volta era, GPU-poor labs | Volta, 32GB HBM2, NVLink-capable, passive server cooling | Mid-range |
| PNY NVIDIA A2 16GB Ampere AI Graphics Card | Low-power inference and edge/1U deployment | Ampere, 16GB GDDR6, low-profile, low TDP, passive/server airflow | Mid-range |
| Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo | Maximum VRAM per card, large-model inference | Intel Arc Pro, dual-GPU 48GB total, turbo cooling | Premium |
| GIGABYTE Radeon AI PRO R9700 AI TOP 32G | Modern single-card training and inference | 32GB GDDR6, turbo fan cooling, GV-R9700AI TOP-3, ROCm-oriented | Premium |
How We Chose
We built this list around what a machine learning practitioner can actually load, train, and deploy, not gaming benchmarks. The first filter was VRAM capacity, because memory, not compute, is what stops most ML workflows: a model’s weights plus optimizer state plus activations must fit in GPU memory or you fall back to slow host-offload. The second filter was software ecosystem support, separating cards with mature CUDA paths, cards with growing ROCm paths, and cards relying on community-maintained Intel tooling. The third was the practical environment a card lives in — a passive datacenter accelerator needs different airflow and power than a consumer triple-fan board, and that changes who should buy it. We also weighed memory bandwidth, since batch throughput is bandwidth-bound more often than people expect, and considered multi-GPU scaling, because two cheap cards only beat one good card when the framework and interconnect cooperate. Finally, we mapped each card to a price tier and a realistic workload class so readers can match budget to model size. This is a research-based roundup drawing on published specifications and vendor documentation; we did not test these cards ourselves.
1. ASRock Radeon RX 7600 Challenger Pro 8GB OC – Best for Budget Entry into ML

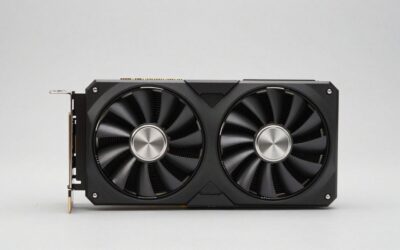
ASRock Radeon RX 7600 Challenger Pro 8GB OC, AMD RDNA 3, 8GB GDDR6, PCIe 4.0, Triple Fans, 0dB Silent, 2695MHz Boost, Triple Fan Graphics Card
Included for 'Best Graphics Cards (GPUs) for Machine Learning' because the listing specifies AMD RDNA 3 and 8GB GDDR6, details this guide uses to compare options.
View on AmazonThis is the card to buy when you want to learn machine learning on a GPU without spending workstation money. The ASRock Radeon RX 7600 Challenger Pro 8GB OC is an AMD RDNA 3 board with 8GB of GDDR6 on a PCIe 4.0 interface, a triple-fan cooler, a 0dB silent mode that stops the fans at low load, and a rated boost clock of 2695MHz. For someone running their first PyTorch or TensorFlow experiments, fine-tuning small models, or doing inference on quantized networks, it turns a frustratingly slow CPU-only workflow into something interactive.
Who it suits: students, self-taught engineers, and tinkerers who want a legitimate GPU compute device at the lowest sensible entry price. It is also a reasonable choice for a secondary development machine where you prototype code that will later run on rented cloud hardware.
Key specifications to keep in mind:
- Architecture: AMD RDNA 3, which means ROCm is the relevant compute stack rather than CUDA.
- Memory: 8GB GDDR6. This is the defining constraint — it caps model size hard.
- Interface: PCIe 4.0, so it slots into any modern board without bandwidth being the bottleneck for a single card.
- Cooling: Triple fans with a 0dB silent mode, appropriate for a desktop tower and quiet enough for a home office.
- Boost clock: 2695MHz, a competitive figure in its class.
Strengths. The appeal is straightforward: it is a current-generation, driver-supported GPU with modern display capabilities that doubles as a perfectly good gaming card. ROCm support for RDNA 3 has improved steadily, and for inference of quantized models — 4-bit and 8-bit weight formats — 8GB goes further than the raw number suggests. A 7B-parameter model at 4-bit quantization fits comfortably, and small vision models like classification or detection backbones train without constant out-of-memory errors. The triple-fan design keeps sustained loads from thermal-throttling in a normal case, and the 0dB mode means it is silent when you are just writing code.
Pros
- Lowest-cost legitimate path to GPU-accelerated ML among current-generation cards.
- Modern RDNA 3 architecture with ongoing ROCm improvements.
- Doubles as a capable gaming and general-purpose GPU.
- Quiet triple-fan cooling with a 0dB idle mode.
- PCIe 4.0 keeps single-card bandwidth simple.
Cons
- 8GB VRAM is a hard ceiling; most real fine-tuning jobs exceed it.
- ROCm is less mature than CUDA, so some libraries and tutorials need extra setup.
- No tensor-core equivalent class of mixed-precision acceleration to the same degree as NVIDIA’s recent parts.
- Not viable for training anything beyond small models without heavy gradient checkpointing or offload.
- Passive multi-GPU ambitions are unrealistic on a consumer board like this.
How it compares with the nearest alternative. The nearest competitor is the NVIDIA Tesla K40, the other budget-tier card on this list. The RX 7600 is far newer and runs Rings around the K40 in efficiency, driver support, and power draw — the K40 is a Kepler-era datacenter part with no modern mixed-precision training story, while the RX 7600 is a current consumer board. The trade-off: the K40 has a larger memory capacity in its class (roughly 12GB of GDDR5), which matters if you need to hold a slightly bigger model than 8GB allows and can tolerate ancient tooling. For anyone starting fresh in 2026, the RX 7600 is the saner purchase; the K40 only makes sense for specific legacy work.
2. NVIDIA Tesla K40 – Best for Legacy Kepler Compute on a Tight Budget

NVIDIA Tesla K40 GPU Computing Processor Graphic Cards 900-22081-2250-000
Included for 'Best Graphics Cards (GPUs) for Machine Learning' as a relevant option in this category; details come from the product listing.
View on AmazonThe NVIDIA Tesla K40 is a datacenter accelerator from the Kepler generation, sold under part number 900-22081-2250-000. It belongs to the class of passive, server-oriented cards that were designed to sit in rack airflow rather than a desktop tower. If you find one cheaply and you specifically need a CUDA-capable card with more memory than an 8GB consumer board — roughly 12GB of GDDR5 in this class — it can serve as a blunt instrument for small model work. But it is a relic, and you should buy it with eyes open.
Who it suits: hobbyists who want a very cheap CUDA device for learning the basics, people maintaining legacy code that targets older CUDA toolkits, and tinkerers building a home lab around second-hand server parts. It does not suit anyone who needs to train modern transformer models or run current frameworks without hassle.
Key specifications and practical notes:
- Architecture: Kepler, which sits several generations behind current NVIDIA parts. Modern CUDA toolkits have dropped support for Kepler, so you are pinned to older driver and toolkit versions.
- Memory: Approximately 12GB of GDDR5 in this class — more capacity than an entry consumer card, but far slower bandwidth than modern GDDR6 or HBM.
- Form factor: Passive cooling, meaning no onboard fan. It expects server chassis airflow; in a desktop case you must add directed airflow or it will overheat.
- Power: Datacenter-class power connectors and draw, which usually means an adapter or a PSU with the right leads.
Strengths. The honest appeal is price and CUDA. Despite its age, it is a genuine NVIDIA compute card, so CUDA exists. That means the enormous body of CUDA tutorials, libraries, and Stack Overflow answers theoretically apply, even if the specific toolkit version is old. Its larger-than-entry memory capacity means you can load a model that would not fit on an 8GB consumer card. For pure FP32 single-precision compute — the classic scientific computing workload — it still does work. If you are learning CUDA programming itself rather than ML specifically, a cheap Kepler card is a legitimate sandbox.
Pros
- CUDA support, even if restricted to older toolkit versions.
- Larger memory capacity than entry-level consumer cards of its generation.
- Very low second-hand cost; sometimes available for the price of a nice dinner.
- Fine for pure FP32 scientific computing and CUDA learning.
- Datacenter build quality means it tolerates sustained load if cooled properly.
Cons
- Kepler is end-of-life for modern CUDA; current frameworks may not run at all without patching.
- No usable tensor-core or mixed-precision training path.
- Passive cooling makes it awkward or unsafe in a normal desktop case.
- Slow GDDR5 bandwidth throttles throughput badly by modern standards.
- Power connectors and server form factor add friction to building a machine around it.
How it compares with the nearest alternative. Against the ASRock RX 7600, the K40 loses decisively on software relevance and efficiency. The RX 7600 runs current ROCm and current frameworks; the K40 runs a frozen slice of CUDA history. The K40’s only edges are its larger memory class and the fact that it is NVIDIA hardware, which matters if you specifically need CUDA semantics rather than ROCm. Against the NVIDIA Tesla V100, the K40 is completely outclassed — the V100 has HBM2, tensor cores, and a modern-enough CUDA path, and it costs more for exactly that reason. Think of the K40 as a curiosity or a teaching aid, not a working ML accelerator.
3. NVIDIA Tesla V100 Volta 32GB – Best for Affordable Tensor-Core Training Power

NVIDIA Tesla V100 Volta GPU Accelerator 32GB Graphics Card
Included for 'Best Graphics Cards (GPUs) for Machine Learning' as a relevant option in this category; details come from the product listing.
View on AmazonThe NVIDIA Tesla V100 Volta GPU Accelerator with 32GB is the card that defined a generation of deep learning hardware. It was the first widely deployed NVIDIA part with tensor cores, the specialized units that accelerate the matrix math at the heart of neural networks, and its 32GB of HBM2 memory made large models practical years before consumer cards caught up. In 2026, second-hand V100s are a fixture of budget ML labs and home servers, and for good reason.
Who it suits: researchers and serious hobbyists who want real tensor-core training performance for a fraction of current datacenter prices. It is the sweet spot for people fine-tuning medium models, training from scratch on datasets that fit in 32GB, or running inference at scale. It is not for someone who wants a plug-and-play desktop card.
Key specifications and practical notes:
- Architecture: Volta, the first Tensor Core generation. Mixed-precision (FP16) training is where it shines.
- Memory: 32GB HBM2 — high-bandwidth memory that delivers far more throughput than GDDR of the same era.
- Interconnect: NVLink-capable, which is the crucial detail for multi-GPU work. NVLink lets two or more V100s communicate at very high bandwidth, dramatically improving multi-GPU scaling versus PCIe-only setups.
- Form factor: Passive server cooling, typically SXM or PCIe variants depending on the exact model. Expect to provide airflow.
- Power: Datacenter-class draw, so plan a PSU and cooling solution accordingly.
Strengths. The V100’s combination of tensor cores, HBM2 bandwidth, 32GB capacity, and NVLink is still potent. For FP16 training, it remains genuinely capable, and 32GB holds a surprising range of models, especially with gradient checkpointing and mixed precision. HBM2 bandwidth means batch throughput stays high, so your GPUs are less often starved for data. NVLink is the quiet superpower: if you buy two V100s, they scale far better than two consumer cards chained over PCIe, which makes a dual-V100 used server a legitimate small training rig. And because a huge amount of ML software matured alongside Volta, compatibility is broad — most frameworks still recognize and support it.
Pros
- Tensor cores and HBM2 make it far faster than its age suggests.
- 32GB capacity handles medium models and larger batches.
- NVLink enables strong multi-GPU scaling.
- Broad framework and CUDA compatibility from its era of dominance.
- Second-hand pricing is a fraction of a new datacenter card of similar capacity.
Cons
- Passive cooling demands a server chassis or dedicated airflow.
- High power draw and datacenter connectors add build cost.
- Volta lacks the newer mixed-precision and sparsity features of later architectures.
- No display outputs — it is a compute-only card.
- Newer frameworks increasingly optimize for Ampere-and-later tensor core instruction sets.
How it compares with the nearest alternative. The closest comparison in this list is the PNY NVIDIA A2 16GB. Both are NVIDIA compute cards, but they occupy opposite ends of the spectrum: the V100 is a high-power, high-bandwidth training workhorse with 32GB and NVLink, while the A2 is a low-power inference card with 16GB and a tiny thermal envelope. If you are training, the V100 wins on every axis except power and cooling convenience. If you are deploying inference in a small chassis or running 24/7 with low electricity cost, the A2 is the better fit. Against the GIGABYTE R9700, the V100 has more mature tensor-core software support but gives up modernity and single-card convenience.
4. Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo – Best for Maximum VRAM Capacity

Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo Graphics Card
Included for 'Best Graphics Cards (GPUs) for Machine Learning' as a relevant option in this category; details come from the product listing.
View on AmazonWhen your problem is not speed but capacity, this is the card to consider. The Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo presents a 48GB total memory pool using Intel’s Arc Pro architecture in a dual-GPU configuration with turbo cooling. In plain terms: it is the card for someone who needs to hold a large model’s weights in GPU memory and does not want to build a multi-card rig to get there.
Who it suits: practitioners running large language models locally, working with big vision models, or doing inference on networks that simply do not fit in 24GB or 32GB. It suits people willing to work with Intel’s software stack and its evolving toolchain. It does not suit someone who needs the deepest, most battle-tested CUDA or ROCm ecosystem with zero friction.
Key specifications and practical notes:
- Configuration: Dual-GPU design presenting a combined 48GB memory pool, cooled with a turbo-fan system.
- Architecture class: Intel Arc Pro, Intel’s professional/workstation lineup aimed at AI and content workloads.
- Software stack: Intel’s oneAPI and related AI tooling, which has matured significantly but is not as universally supported as CUDA.
- Form factor: Active turbo cooling, so unlike the passive Tesla cards it can live in a desktop tower.
- Memory bandwidth: Because it is a dual-GPU arrangement, effective bandwidth depends on how your framework shards the workload across the two GPUs; unified capacity is not the same as unified bandwidth.
Strengths. Capacity is the headline, and it is a real advantage. A 48GB pool lets you load parameter counts that would otherwise require two or three cards, and because it is one physical card with active cooling, you skip the airflow engineering that passive datacenter parts demand. For inference — where you mostly read weights and generate tokens — a large, adequately-fast memory pool is exactly what you want, and this card delivers it in a single slot. Intel has invested heavily in its AI software stack, and for standard inference frameworks the experience is increasingly smooth. For batch inference serving many requests, the dual-GPU design can process work in parallel.
Pros
- Largest memory capacity on this list at 48GB.
- Active turbo cooling works in a normal desktop case.
- One card, one slot — no multi-card motherboard or riser complexity.
- Strong for large-model inference where capacity beats raw compute.
- Intel’s professional driver branch targets AI and workstation reliability.
Cons
- Intel’s AI software ecosystem is less mature than CUDA, so some libraries need extra work.
- Dual-GPU sharding means real-world bandwidth depends on framework support.
- Capacity does not equal training speed; fine-tuning may be slower than dedicated training cards.
- Fewer community tutorials and prebuilt recipes than the NVIDIA equivalents.
- Premium price tier for the capacity it provides.
How it compares with the nearest alternative. The natural rival is the GIGABYTE Radeon AI PRO R9700 with 32GB. The Arc Pro B60 Dual wins on raw capacity — 48GB versus 32GB — which matters if your model falls in that gap. The R9700 wins on software maturity (ROCm has a longer track record in ML than Intel’s stack) and on single-GPU simplicity, since the Arc card’s dual configuration introduces workload-sharding considerations. If your model fits in 32GB, the R9700 is the cleaner choice. If it does not, the Arc Pro B60 Dual is the one that lets you load it at all.
5. GIGABYTE Radeon AI PRO R9700 AI TOP 32G – Best Overall for Modern ML Workstations

GIGABYTE Radeon™ AI PRO R9700 AI TOP 32G Graphics Card, Turbo Fan Cooling System, 32GB GDDR6, GV-R9700AI TOP-32GD Video Card
Included for 'Best Graphics Cards (GPUs) for Machine Learning' because the listing specifies Turbo Fan Cooling System and 32GB GDDR6, details this guide uses to compare options.
View on AmazonThis is the card we recommend to most people who want one serious accelerator for machine learning in 2026. The GIGABYTE Radeon AI PRO R9700 AI TOP 32G is a purpose-positioned AI workstation card with 32GB of GDDR6, a turbo fan cooling system, and the model designation GV-R9700AI TOP-3. It sits in AMD’s professional AI lineup, meaning it is built and marketed for exactly the workloads this guide is about, not adapted from a gaming card after the fact.
Who it suits: engineers, researchers, and serious hobbyists building a single-GPU workstation who want modern architecture, ample memory, active cooling that fits a tower case, and a software stack that AMD actively supports for AI. It is the best balance of capacity, current-generation support, and practical installation on this list.
Key specifications and practical notes:
- Memory: 32GB GDDR6 — enough for mid-size model fine-tuning, diffusion training, and large-model inference with quantization.
- Cooling: Turbo fan cooling system, meaning it is an actively cooled card suited to a standard desktop chassis rather than a server rack.
- Software stack: AMD ROCm, which the company has invested in heavily for its professional AI line. Expect the best-supported ROCm experience on current AMD hardware.
- Positioning: The “AI PRO” and “AI TOP” naming signals a workstation/creator target audience, which typically correlates with longer validation cycles and professional driver branches.
- Power and installation: Standard PCIe workstation card form factor with the power connectors typical of its class; plan a PSU with headroom.
Strengths. The R9700’s case is balance. Thirty-two gigabytes is the sweet spot for a single-card ML workstation in 2026 — large enough to fine-tune most open models with mixed precision and parameter-efficient methods, small enough that the card is not priced like a datacenter part. Because it is a current-generation AMD AI card, ROCm support is a first-class concern for the vendor rather than an afterthought, which translates to fewer driver surprises than older or repurposed hardware. Active turbo cooling means you can install it in a normal case without engineering server airflow. And as a professional AI card, it avoids the display-less, connector-awkward nature of the Tesla parts — it is designed to be a complete, installable workstation component.
Pros
- 32GB GDDR6 covers a wide range of real training and inference workloads.
- Purpose-built and vendor-positioned for AI work.
- Actively cooled and desktop-friendly.
- Best-supported modern ROCm experience among AMD options here.
- Balanced capacity, power, and price for a single-card build.
Cons
- ROCm still trails CUDA in breadth of library support and tutorial availability.
- 32GB is generous but not unlimited; the largest models still need quantization or sharding.
- Premium price tier.
- Multi-GPU scaling across several of these cards is possible but less turnkey than NVIDIA NVLink setups.
- Some niche research code assumes CUDA and needs porting.
How it compares with the nearest alternative. Its closest competitors are the two cards above and below it in capacity: the Arc Pro B60 Dual 48GB and the Tesla V100 32GB. Against the Arc card, the R9700 trades 16GB of capacity for a more mature software stack and simpler single-GPU execution — for most users, the better trade. Against the V100, the R9700 wins on modernity, active cooling, power efficiency, and vendor support, while the V100 counters with mature tensor-core software and NVLink multi-GPU scaling. If you are building one machine in 2026 and want the fewest headaches, the R9700 is the pick; if you are assembling a multi-GPU training cluster from used parts, the V100’s NVLink remains compelling.
6. PNY NVIDIA A2 16GB Ampere AI Graphics Card – Best for Low-Power Inference

PNY NVIDIA A2 16GB Ampere AI Graphics Card
Included for 'Best Graphics Cards (GPUs) for Machine Learning' as a relevant option in this category; details come from the product listing.
View on AmazonThe PNY NVIDIA A2 16GB is a different kind of card from everything else here. It is an Ampere-generation NVIDIA AI accelerator with 16GB of GDDR6, a low-profile form factor, and a low thermal design power. It is not built to win training races. It is built to run inference efficiently, quietly, and continuously, often in space-constrained or power-constrained environments.
Who it suits: anyone deploying models for serving rather than training, edge or appliance builders, and people running a 24/7 inference box where electricity and heat matter. It also suits small-form-factor workstation builds. It does not suit someone whose primary goal is training large models.
Key specifications and practical notes:
- Architecture: Ampere, which includes tensor cores and a mature CUDA path — a big compatibility advantage over the Kepler K40 and an efficiency advantage over the Volta V100.
- Memory: 16GB GDDR6, a solid middle ground for inference workloads with quantized models.
- Form factor: Low-profile, designed for compact chassis and dense servers. Expect it to rely on chassis airflow in server settings.
- Power: Low TDP relative to training cards, which is the entire point — it can run continuously without a beefy PSU or heavy cooling.
- Software stack: Full CUDA support, so nearly every inference framework works with minimal setup.
Strengths. The A2’s value proposition is efficiency plus ecosystem. Because it is Ampere with CUDA, it runs essentially any inference framework you throw at it — TensorRT, ONNX Runtime, PyTorch, and the rest — with the compatibility that only NVIDIA’s stack provides. Its low power draw means you can build a quiet, cool machine, or fit several into a 1U server, and it will not blow your electricity budget running around the clock. The low-profile design opens up small-form-factor builds that no full-height card can touch. For serving a quantized model to a handful of users, it is exactly right, and 16GB is enough for many useful quantized models.
Pros
- Mature CUDA support for friction-free inference deployment.
- Low power draw enables 24/7 operation cheaply.
- Low-profile form factor fits compact and dense builds.
- Ampere tensor cores give respectable inference throughput.
- 16GB handles many quantized models comfortably.
Cons
- Not intended for training — capacity and compute are inference-oriented.
- Server variants rely on chassis airflow rather than a large onboard fan.
- 16GB limits model size for larger networks.
- Price-per-unit-of-compute is poor if you actually want to train.
- Low-profile cooling must be matched to your case.
How it compares with the nearest alternative. Compared with the Tesla V100 32GB, the A2 gives up training muscle and half the capacity in exchange for dramatically lower power, a modern CUDA path, and a compact form factor. If your workload is inference, that is a good trade; if it is training, take the V100. Compared with the GIGABYTE R9700, the A2 offers NVIDIA software maturity and efficiency but far less capability — the R9700 can both train and infer, while the A2 is specialized for serving. Treat the A2 as an appliance-grade inference card, not a general-purpose accelerator.
How to Choose
Choosing a GPU for machine learning comes down to matching four numbers to your workload: VRAM capacity, memory bandwidth, supported software stack, and power/cooling budget. Get those right and everything else is detail. Here is how to reason about each, with concrete values.
Start with VRAM capacity, because it is a hard wall
Memory capacity is the single most common reason a workflow fails. A model must hold its weights in GPU memory, and during training it also holds gradients and optimizer state. A rough planning rule for full fine-tuning in mixed precision is to budget roughly 16–20 bytes of GPU memory per parameter once you account for weights, gradients, optimizer state, and activations — though the exact figure varies with batch size, sequence length, and whether you use techniques like gradient checkpointing or 8-bit optimizers. That means:
- 8GB: fine-tuning very small models, or inference of quantized models up to roughly 7B parameters at 4-bit.
- 16GB: LoRA and adapter-based fine-tuning of mid-size models, inference of larger quantized models.
- 32GB: full or parameter-efficient fine-tuning of most open models in the 7B–13B range, plus comfortable inference of larger quantized models.
- 48GB+: large-model inference and heavier fine-tuning where the weights simply will not fit on 24 or 32GB.
Two techniques change these thresholds. Quantization (storing weights in 4-bit or 8-bit) roughly halves or quarters the memory a model needs for inference, at some accuracy cost. Parameter-efficient fine-tuning like LoRA trains a small number of extra weights instead of updating everything, cutting optimizer memory dramatically. If you rely on these, a smaller card goes further — but they add complexity and sometimes limit what you can achieve.
Then decide between CUDA, ROCm, and Intel’s stack
Software support determines how much of your time goes to modeling versus troubleshooting. CUDA is the broadest and most mature ecosystem — nearly every model, library, and tutorial assumes it. ROCm, AMD’s stack, has improved substantially and now covers the major frameworks, but some niche libraries lag and setup can require care. Intel’s oneAPI-based AI tooling has matured quickly and works well for standard inference, but has the smallest body of community recipes. A practical rule: if a specific paper’s code or a niche library is essential to your work, verify it supports your chosen stack before buying. If you mostly run mainstream models through mainstream frameworks, all three are viable, with CUDA requiring the least babysitting and ROCm/Intel offering better value per gigabyte of VRAM.
Check memory bandwidth, because throughput is often bandwidth-bound
VRAM capacity decides what fits; memory bandwidth decides how fast it moves. Inference in particular is frequently bandwidth-bound — generating each token requires reading the model’s weights, so the speed at which memory can feed the compute units sets the ceiling. This is why HBM2 on the V100 can outperform newer GDDR-based cards in some memory-bound tasks despite lower nominal compute. Bandwidth also matters for training batch throughput: if the GPU finishes a matrix operation before the next batch of data arrives, you are wasting silicon. Datacenter memory (HBM) generally offers the highest bandwidth; consumer and workstation GDDR6 is lower but still ample for most single-user work. For serving many concurrent requests, bandwidth is one of the first specs to scrutinize.
Plan power and cooling before you buy
This is the part people underestimate. Passive datacenter cards — the K40, the V100, and server variants of the A2 — have no onboard fans and depend on strong front-to-back airflow in a server chassis. Dropping one into a desktop tower without directed airflow will cook it. Actively cooled cards — the RX 7600’s triple fans, the R9700’s turbo fan, the Arc Pro B60 Dual’s turbo cooling — can live in a normal case. Then budget power: a single high-end workstation card typically wants a quality PSU with several hundred watts of headroom, and multi-GPU setups multiply that. As a worked example, if you plan a two-card build and each card draws around 250–300W under load, plus roughly 150W for CPU, motherboard, drives, and fans, you are looking at a sustained draw in the 650–750W range, which argues for an 850W–1000W 80 Plus Gold unit to keep the PSU in its efficiency sweet spot and leave transient headroom. Add case fans sized to move that much heat, and confirm your motherboard has the PCIe lanes and physical spacing for two cards — many consumer boards split a single x16 slot into x8/x8 when both are populated, which is usually fine for ML but worth knowing.
Evaluate multi-GPU scaling realistically
Two cheaper cards do not simply add up to one better card. Multi-GPU training requires the framework to split the model or the data across devices and synchronize gradients, and the synchronization happens over PCIe or a faster interconnect. NVLink, present on the V100, lets cards exchange data at very high bandwidth and scales much better than PCIe-only setups. On PCIe-only systems, scaling efficiency drops as the number of GPUs grows, and the communication overhead can eat much of the theoretical gain. Before committing to multi-GPU, ask whether your model even shards cleanly, whether your framework supports the parallelism you intend, and whether your motherboard and power supply can support the cards. For many single users, one 32GB card is a smoother path than two 16GB cards with a communication bottleneck.
A decision matrix for common situations
| Your situation | Capacity needed | Recommended pick |
|---|---|---|
| Learning ML, small models, tight budget | 8GB | ASRock Radeon RX 7600 Challenger Pro 8GB OC |
| Legacy CUDA code or cheap FP32 tinkering | ~12GB class | NVIDIA Tesla K40 (only if very cheap) |
| Deploying quantized model inference 24/7 | 16GB | PNY NVIDIA A2 16GB |
| Training medium models, willing to buy used | 32GB | NVIDIA Tesla V100 Volta 32GB |
| Single-card modern ML workstation | 32GB | GIGABYTE Radeon AI PRO R9700 AI TOP 32G |
| Largest models that will not fit in 32GB | 48GB | Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo |
Match the card to the model workload
Think in workload classes rather than model names. Small vision and tabular models — classification, detection backbones, small transformers — train fine on 8–16GB. Transformer fine-tuning is where 24–32GB becomes the practical minimum for comfortable work, or 16GB with aggressive parameter-efficient methods. Diffusion model training is memory-hungry because of large activations, so 24–32GB is again the realistic floor. Large language model inference is a capacity game: quantization plus enough VRAM to hold the weights, which pushes you toward 32GB or 48GB. Batch inference serving rewards bandwidth and capacity together, making the A2 attractive at low power or the R9700 attractive for heavier loads. Decide which class you live in, and the capacity decision usually makes itself.
Weigh value against upgrade path
Finally, look past the purchase price to the total path. New current-generation cards cost more but come with vendor support, modern drivers, efficiency, and resale value. Used datacenter cards are cheaper per gigabyte of VRAM but bring cooling requirements, power demands, end-of-life software risks, and no warranty. A used V100 can be excellent value for training — until a framework drops Volta optimization. A current AMD or Intel AI card costs more but should stay relevant and supported longer. If this is a machine you will use for two or three years and grow with, paying for current-generation support usually beats saving on a relic; if this is a sandbox or a stepping stone, the used route is defensible.
Frequently Asked Questions
How much VRAM do I actually need for machine learning?
For inference of quantized models, 8GB handles small models and 16GB is comfortable for mid-size ones. For fine-tuning, 24–32GB is the practical sweet spot in 2026, because training holds weights, gradients, optimizer state, and activations simultaneously. For large models that exceed what 32GB can hold, 48GB or a multi-GPU setup becomes necessary.
Is CUDA required, or does ROCm work for ML?
ROCm works well for mainstream frameworks and models, and AMD has invested heavily in its professional AI cards to make the experience smoother. CUDA still has broader coverage of niche libraries and the largest body of tutorials. If you depend on specific research code, check its stack support before choosing; otherwise ROCm is a legitimate path with strong value.
Can I use a gaming GPU for machine learning?
Yes, and many people do. Gaming cards share the same core compute hardware and usually have good driver support; the main limitation is VRAM capacity and sometimes reduced double-precision performance. A current consumer card is a perfectly reasonable entry point for learning and small-to-medium workloads.
Do I need multiple GPUs?
Usually no. One high-capacity card is simpler, cheaper in power and cooling, and avoids the communication overhead that limits multi-GPU scaling. Multiple GPUs make sense when your model does not fit on one card or when you are training at a scale where throughput justifies the complexity. If you do go multi-GPU, prefer a fast interconnect like NVLink where available.
Why do datacenter cards like the Tesla V100 and K40 need special cooling?
They are designed as passive cards with no onboard fans, intended for server chassis that push air front-to-back across the components. In a desktop tower without that directed airflow, they overheat. Actively cooled workstation and consumer cards are the safer choice for a normal case.
Does memory bandwidth matter more than compute for inference?
For single-request inference, it often does, because generating each token requires reading the model’s weights from memory, making bandwidth the bottleneck. For batch inference and training, compute and bandwidth both matter. This is why HBM-based cards can outperform their nominal compute in memory-bound tasks.
How large a power supply do I need for an ML build?
Budget several hundred watts of headroom above your peak component draw. As a worked example, two cards at roughly 250–300W each plus about 150W for the rest of the system points to a sustained draw near 650–750W, so an 850W–1000W 80 Plus Gold unit keeps you efficient and covers transients. Single-card builds need far less.
Is it worth buying a used datacenter GPU in 2026?
It can be excellent value, especially for training where capacity and bandwidth matter more than age. But factor in passive cooling requirements, high power draw, special connectors, the risk of software support ending, and no warranty. A used V100 is a strong training bargain; a Kepler-era card is best treated as a curiosity.
Final Recommendation by Situation
If you are building a single modern ML workstation and want the fewest headaches, buy the GIGABYTE Radeon AI PRO R9700 AI TOP 32G — its 32GB, active cooling, and mature-by-2026 ROCm make it the most balanced choice. If your work is deploying inference around the clock in a compact or power-sensitive machine, the PNY NVIDIA A2 16GB is the right tool. If you are assembling a budget training rig from used parts and want multi-GPU scaling, a Tesla V100 32GB — ideally a pair with NVLink — offers the best cap-per-dollar. If your model simply will not fit in 32GB, the Bornffinally MAXSUN Intel Arc Pro B60 Dual 48G Turbo gives you the capacity to load it. If you are just starting and want to spend as little as possible, the ASRock Radeon RX 7600 Challenger Pro 8GB OC is the honest entry point — and if you can find a Tesla K40 for pocket change and want a CUDA sandbox, it remains a cheap curiosity rather than a serious accelerator.
Ready to decide? Our #1 pick for 2026 is the ASRock Radeon RX 7600 Challenger Pro 8GB OC.
Live price & availability on Amazon.